When the machine boots but the reply disappears
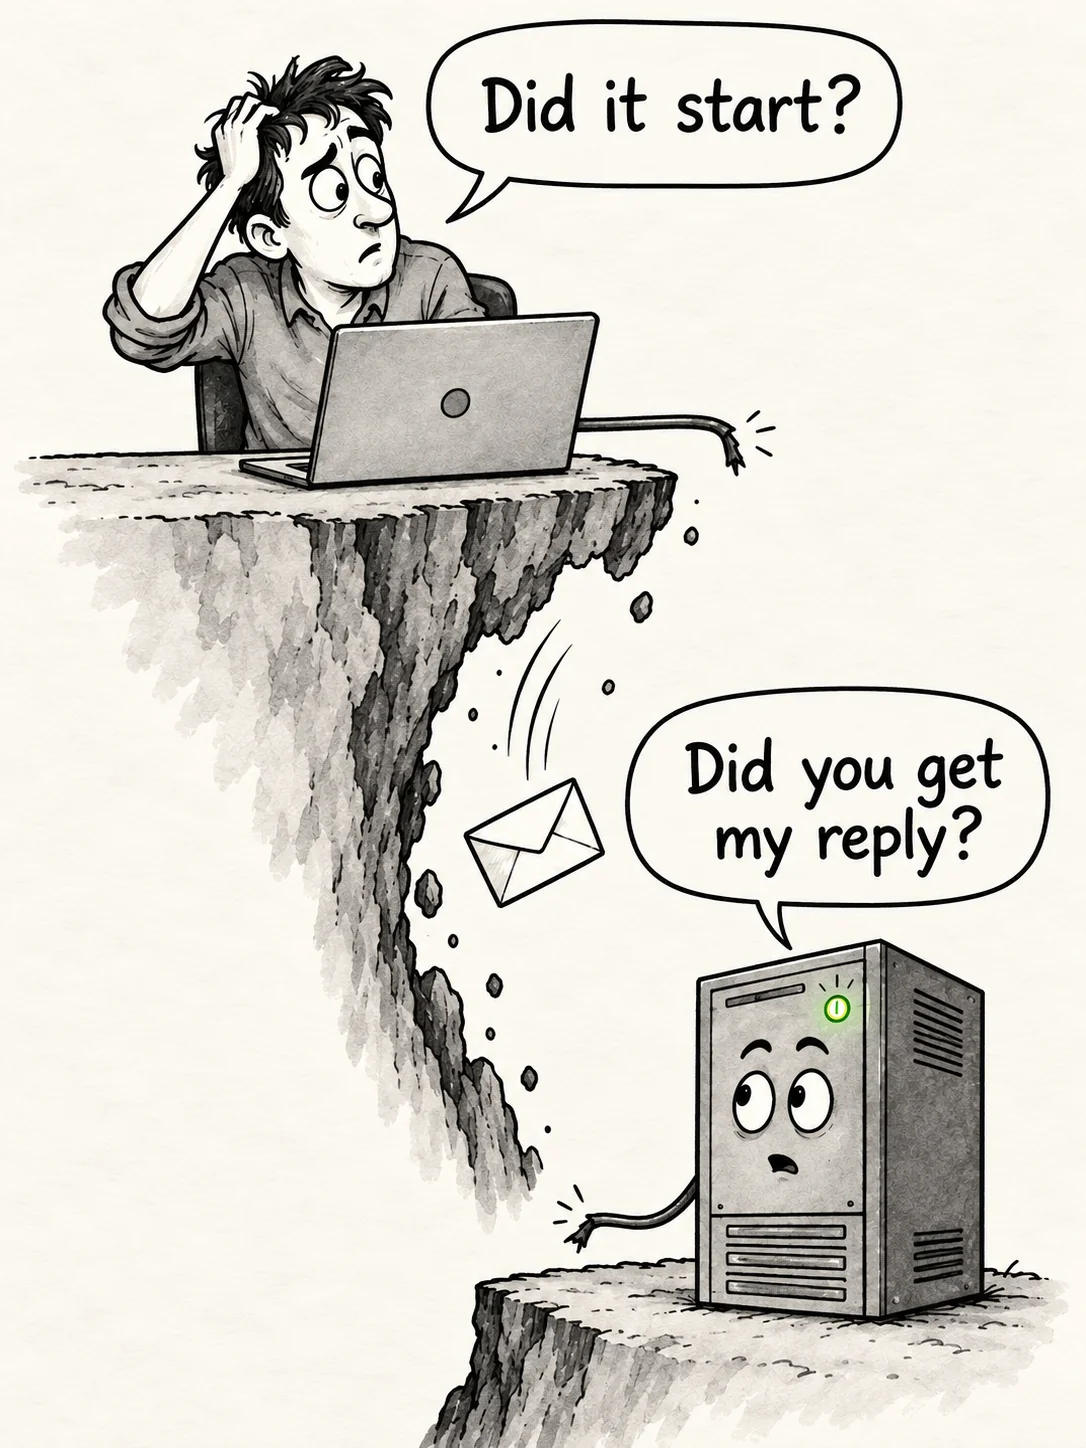
A create request times out. Your client has no answer, but the Linux machine may already be running. Retry with a new request and you could end up paying for two machines. Give up and you could abandon the one doing your work. Neither is a great recovery strategy.
Mainbrella saves a creation receipt before it asks the machine to boot. A retry can find that first attempt. The same idea helps us recover commands and saved disks, although a receipt can’t recover an answer the server never managed to record.
Consider a Python job that reads data from another container and writes metrics.csv. We’ll call the script analysis.py and its slot c17. This example follows our backend at the October 7, 2026 revision. The API reference and agent workflow cover the request formats.
Reserve the slot before booting
Before that job can run, its account has to get a slot. Suppose two requests arrive with one slot left. If both read “one available,” boot, and update the counter afterward, both win. Discovering the conflict after you’ve started paying for it is too late.
Each account has a Cloudflare Durable Object, a coordinator with persistent storage. It reserves slots, monthly starts, and compute allowance. A separate runtime controller manages each slot’s machine.
The coordinator admits requests one at a time and saves each reservation before asking the runtime to boot. The next request therefore sees an occupied slot. The queue in container-account-core.js keeps that order even when a decision pauses at an await.
We release the lock once the reservation is saved. Holding it until Linux was ready would force every machine to wait for the previous boot, which would be a miserable way to start a batch. The diagram shows overlapping boots after ordered reservations; these intervals aren’t measured startup times.

The admission test deliberately holds readiness checks open while six requests compete for a Builder account’s five slots. Five machines begin booting; the sixth gets a conflict. Nothing has to finish booting for the coordinator to know the account is full.
The coordinator gets its account identity from an API key or login session. A caller can’t choose someone else’s account by supplying an x-mainbrella-user header. The auth adapter establishes ownership before the internal request builder forwards the request.
Write the receipt first
The client includes an Idempotency-Key with POST /containers and saves it before sending the request. Reusing that key asks about the same attempt. Reusing it with a different image, size, or other recorded configuration gets a conflict. A fresh key asks for a fresh start, even if the rest of the request looks identical.
A new key on every retry
- Send a create request with key A. The machine boots; the reply is lost.
- Retry the same configuration with key B.
Key B asks for a new start. If capacity allows, you now have two machines.
Keep the key for the original attempt
- Send a create request with key A. The machine boots; the reply is lost.
- Retry the same configuration with key A.
The saved receipt points back to the original start. No second boot.
The account prepares the slot reservation and a receipt containing the reservation number and configuration fingerprint. It commits them together before dispatching the boot. In container-account-core.js, that write is:
await this.ctx.storage.put({
  [KEY]: state,
  [CREATION_PREFIX + idempotencyKey]:
    creation,
});
The write is atomic. Saving only the reservation could charge for a slot the retry can’t find; saving only the receipt could point to a slot we never reserved. Once both are stored, booting can begin.
If the reply disappears now, a retry with the same key finds the saved receipt. It may report starting during the ninety-second pending window. After that, the coordinator checks the runtime and returns the machine if it’s running. It won’t send another boot just because the first answer is missing.
Receipts last twenty-four hours. A retained key returns creation_no_longer_running if the machine stopped or its slot was reused. Use a new key when you want a replacement. Keep the original key and request together so a timeout doesn’t leave you guessing which attempt to recover.
“Running” means the guest can execute a command. The runtime boots the chosen image with sleep infinity and gives uname -a sixty seconds to succeed. Our Python job still has to install its dependencies and pass its own checks.
An old request meets a new machine
Now suppose the boot request itself is delayed. Its reservation is canceled, c17 is released, and a replacement takes the slot. Then the old boot arrives. The slot name is valid, but the request has no business starting anything there.
We give each admitted start a number. The runtime remembers the newest start it accepted and the newest cancellation, rejecting boots whose numbers are no newer than either. It records a cancellation even when there’s no guest to destroy. Otherwise a canceled boot could arrive late and bring the machine back.

The same check protects cleanup. A late “stop 41” must leave machine 42 running. The runtime’s DELETE path records that cancellation without destroying a newer guest. The account also refuses to let an old successful boot reply clear the replacement’s pending reservation.
Public commands and file requests carry { id, createdAt }. The ID names a reusable slot; the timestamp identifies this particular machine in it. We calculate createdAt as max(now, previousCreatedAt + 1), which keeps identities distinct even if two starts happen in one millisecond or the clock moves backward.
Keep both values. “Clean up c17” is a dangerous instruction once c17 has another occupant. Our regression test reuses the slot before releasing its old boot request, without advancing the clock. A hello-world launch tells you nothing about that failure.
Reserve compute, too
A reserved slot also needs reserved runtime. Otherwise five machines could each see the same remaining allowance and all spend it. The account reserves compute before booting, then settles usage when the machine stops.
The weights in plan-policy.js are one compute unit for Lite, ten for Medium, and twenty-eight for XL. Reserve a Medium for an hour and stop it after five minutes, and most of the reservation comes back. The table uses compute-unit-hours, rounded to three decimals.
| Reserved: 10 units × 1 hour | 10.000 |
|---|---|
| Used: 10 units × 5/60 hours | 0.833 |
| Returned after a confirmed stop | 9.167 |
If we can’t reach the machine, we keep its reservation because it may still be running. An admitted launch also consumes a monthly start even if it fails; settling runtime doesn’t refund the start.
We track runtime in compute-unit-milliseconds. The hard deadline is whichever comes first:
- The end of its plan’s session limit.
- Paid access expiration.
- The next UTC month boundary.
- The time its reserved compute runs out.
An idle deadline can stop the machine sooner. Doing work pushes that deadline back, up to the hard deadline; polling status doesn’t. A Durable Object alarm enforces expiration after the client disappears. A plan change may shorten an existing lease, but it can’t extend the original hard deadline.
A broken billing lookup shouldn’t prevent you from stopping a machine. DELETE checks ownership without requiring a fresh billing resolution, and cleanup can use a saved entitlement while it’s valid. For other checks, we retain the newest entitlement observation and let an unpaid result win a tie. A late paid result mustn’t undo a revocation.
Run the job through a disconnect
With the machine running, we can launch analysis.py. Foreground commands have a sixty-second limit. For a longer analysis, or a result we’ll need after a disconnect, we create a managed execution with its own idempotency key and the machine’s exact { id, createdAt } pair.
Here’s the body for a two-minute POST /containers/executions request:
{
  "argv": [
    "python3",
    "/workspace/analysis.py"
  ],
  "timeoutMs": 120000
}
Complete authenticated request
// machine is the exact { id, createdAt } returned for a running guest.
// Persist executionKey and this request before sending them.
const query = new URLSearchParams(machine);
const response = await fetch(`${apiOrigin}/containers/executions?${query}`, {
  method: 'POST',
  headers: {
    Authorization: `Bearer ${apiKey}`,
    'Content-Type': 'application/json',
    'Idempotency-Key': executionKey,
  },
  body: JSON.stringify({
    argv: ['python3', '/workspace/analysis.py'],
    timeoutMs: 120_000,
  }),
});
if (!response.ok) throw new Error(`Execution HTTP ${response.status}`);
const execution = await response.json(); // Save execution.id.
argv passes literal arguments without building a shell command. We save the execution record in executions.js before starting the process, so a retry can recover the same job. Losing the creation response or closing the output stream leaves it running. Cancellation is explicit.
Output events get increasing sequence numbers. The client reconnects with its last processed sequence as cursor and reads what it missed. Streams last thirty seconds, so reconnecting is normal. The job can run for up to fifteen minutes, subject to its requested timeout and the machine’s remaining lease. The diagram follows a job through one such disconnect.

The runtime retains up to thirty-two executions for one hour from admission. Jobs share a four-operation concurrency limit with foreground commands and file transfers. Output is capped at one MiB and a finite event count; hitting the limit stops the job and marks it truncated. Check the final status, exit code, timeout, and truncation flag before accepting the result. A CSV cut off halfway through a row is still a failed analysis.
A runtime controller restart is harder to recover from. The records survive, but the process handles don’t. Recovery marks unfinished jobs interrupted and destroys their guest if it’s still the current generation. We won’t leave a process running without a way to track it, and we won’t quietly run it again.
That decision can lose an unsaved CSV. Automatically replaying a command that sends invoices can do a lot more damage. The caller has to decide whether the job is safe to repeat.
A service name belongs to a network
Our Python job reads http://data.internal/shards/west. To make that work, we register its generation in a private service network alongside a machine named data, serving on port 8080. The caller needs membership but no listening port of its own.
The runtime determines which account and network the request belongs to. Its outbound interceptor removes reserved identity headers and supplies the account, slot, and generation from trusted configuration. Guest code can’t switch customers by inventing a header.
The service registry resolves data in the source generation’s network. Other accounts and networks can reuse that name. Before opening port 8080, the destination checks that it’s still the generation registered for the service.
Membership can change while the data service is answering. We buffer the bounded response and check again before releasing it; the account also rechecks the caller and both memberships. If the service was detached or replaced during the request, the old authorization doesn’t get to carry the response through.
Refusing that response can’t undo what the application already did. Reading an immutable shard is easy to retry. A payment or task-queue request needs an application operation ID, because the service may have committed its change before routing refused the reply.
This routing supports HTTP with one-MiB bodies and a ten-second timeout. It doesn’t carry WebSockets or arbitrary TCP, so adding .internal to a PostgreSQL hostname won’t make it work. Check deployment enablement and GET /capabilities before using it.
Take the CSV with you
Once the job writes /workspace/metrics.csv, we can download it with a file request carrying the machine’s generation. That endpoint transfers raw bytes up to one MiB. There’s no reason to force a file through stdout and then hope it wasn’t truncated.
Uploads in files.js write a temporary file in the target’s existing parent directory, then rename it over the target. Readers see the old file or the completed new one. Paths are positional arguments rather than interpolated shell text. Writes reject symlink targets; reads can follow links inside the owned guest.
Check the CSV’s rows against its inputs, then copy it out before destroying the machine. If we want to preserve the environment too, we need a saved workspace.
Recovering a saved disk
Saving the disk and stopping the machine involves the account coordinator, the runtime, and the provider performing the capture. There’s no transaction that commits all three at once.
The account reserves save capacity and records the operation. The runtime saves its own receipt, calls snapshotContainer(), and writes the returned provider handle into the receipt. That handle is the address needed to restore the disk. Once the account has copied it into the workspace record, stop: true can destroy the source.
If the runtime saves the handle and then loses its reply to the account, a retry recovers the capture from the receipt. But if the provider accepted the capture and the runtime restarted before saving the handle, we have no address to restore from. We know we tried to save the disk. We can’t claim we have a recoverable workspace.

In that unresolved case, workspaces.js returns workspace_save_unavailable and refuses to repeat the capture. The save path leaves the source intact, although its lease still applies. A new key requests a new capture; it doesn’t recover the missing one.
We reserve the source size’s full disk capacity before capture. Deleting a workspace frees its live workspace quota but doesn’t refund the historical capture budget. The provider may already have performed the capture even when we can’t recover its answer, so treating every ambiguous failure as free would allow unlimited retries.
Restoring a ready workspace consumes a new start and gets a fresh generation. It keeps the saved size and internet policy, and requires a matching image digest. An incompatible image or failed provider restore produces an error. Returning an empty machine as a successful restore would be a nasty surprise.
The workspace contains filesystem state. RAM, running processes, previews, and private-service memberships have to be rebuilt. Our script needs progress saved in files; a restored service needs to start and register again. Quiet the writers before capture too. Saving every byte faithfully doesn’t make half-finished application writes consistent.
Try the awkward cases
You can reproduce the awkward timing with the lifecycle tests. They use simulated provider state, so you can hold back a reply without trying to break a live connection. From a backend checkout, run:
node --test containers/container-account.test.mjs \
  containers/user-container.test.mjs \
  containers/workspaces.test.mjs \
  containers/private-services.test.mjs
Start with stopping and reusing a slot fences old delayed dispatches even in the same millisecond. It releases a delayed request after the slot has a new occupant. Then compare lost snapshot response reconciles receipt without recapture with uncertain capture cannot be repeated in the workspace tests. The first has a saved answer to recover. The second has to leave the source running and admit it doesn’t know.